- Category :Speech Synthesis / Machine Learning
- Stack :Python, Piper-style training assets
- Runtime :board-computer-tts
- Training :human-like-voice-ml
- Outputs :Generated voice and audio artifacts
- Status :Documentation-first workspace

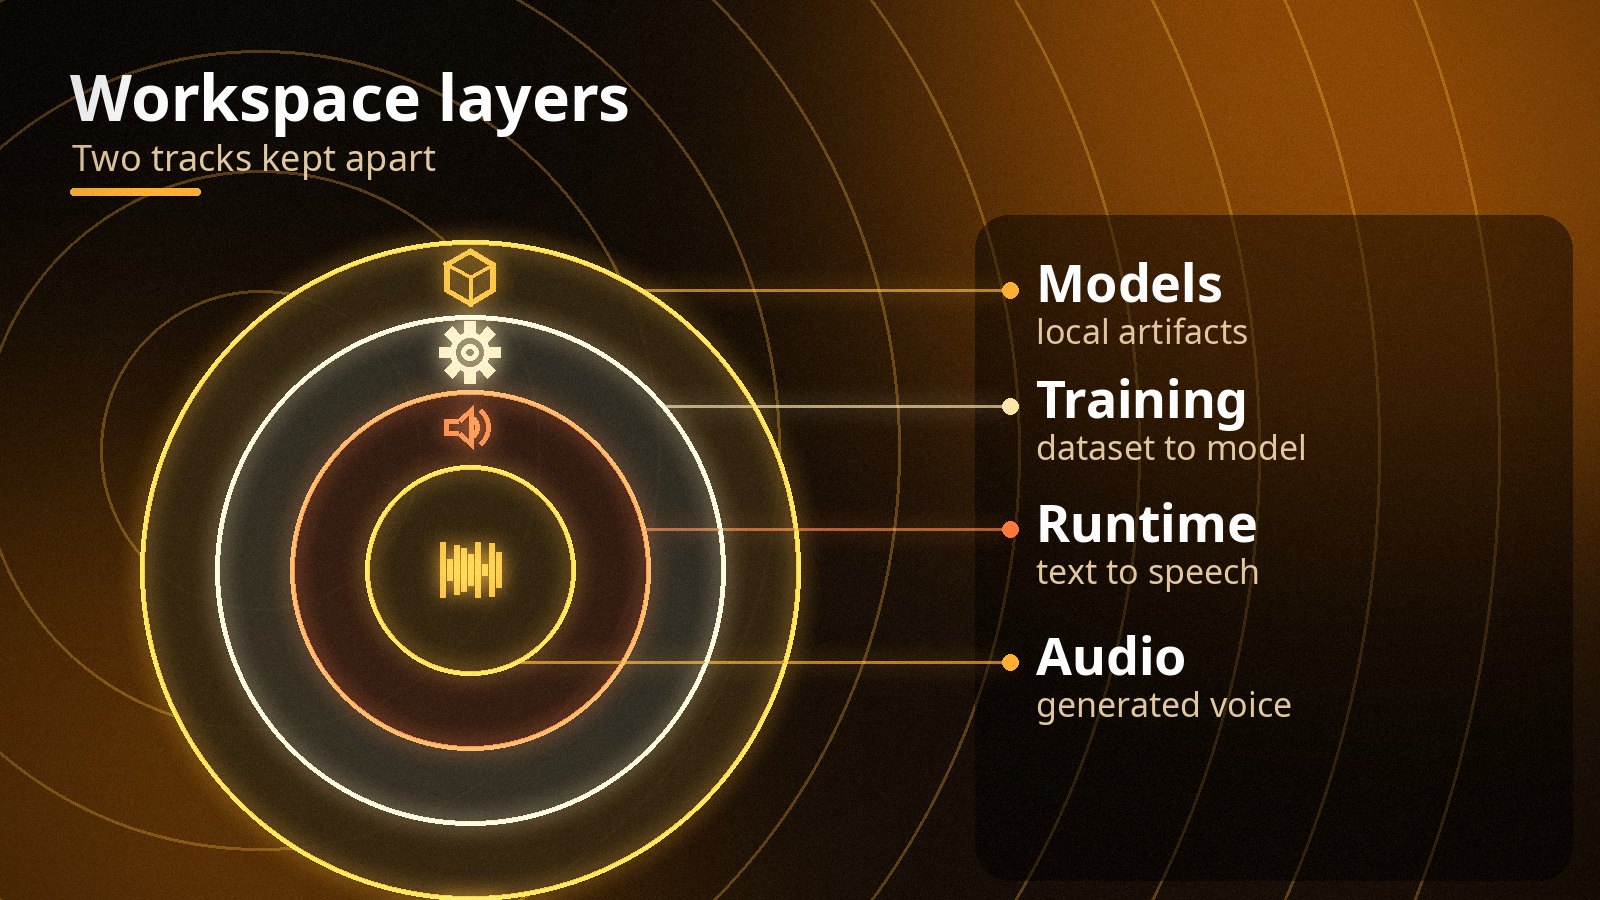
A documentation-first workspace for speech synthesis, divided into two tracks. The runtime track turns input text into generated audio. The training track covers dataset preparation, training and generation of a custom voice model that the runtime can then use.
The workspace keeps the two tracks apart on purpose, because training dependencies, datasets and generated artifacts can be large and environment-specific.
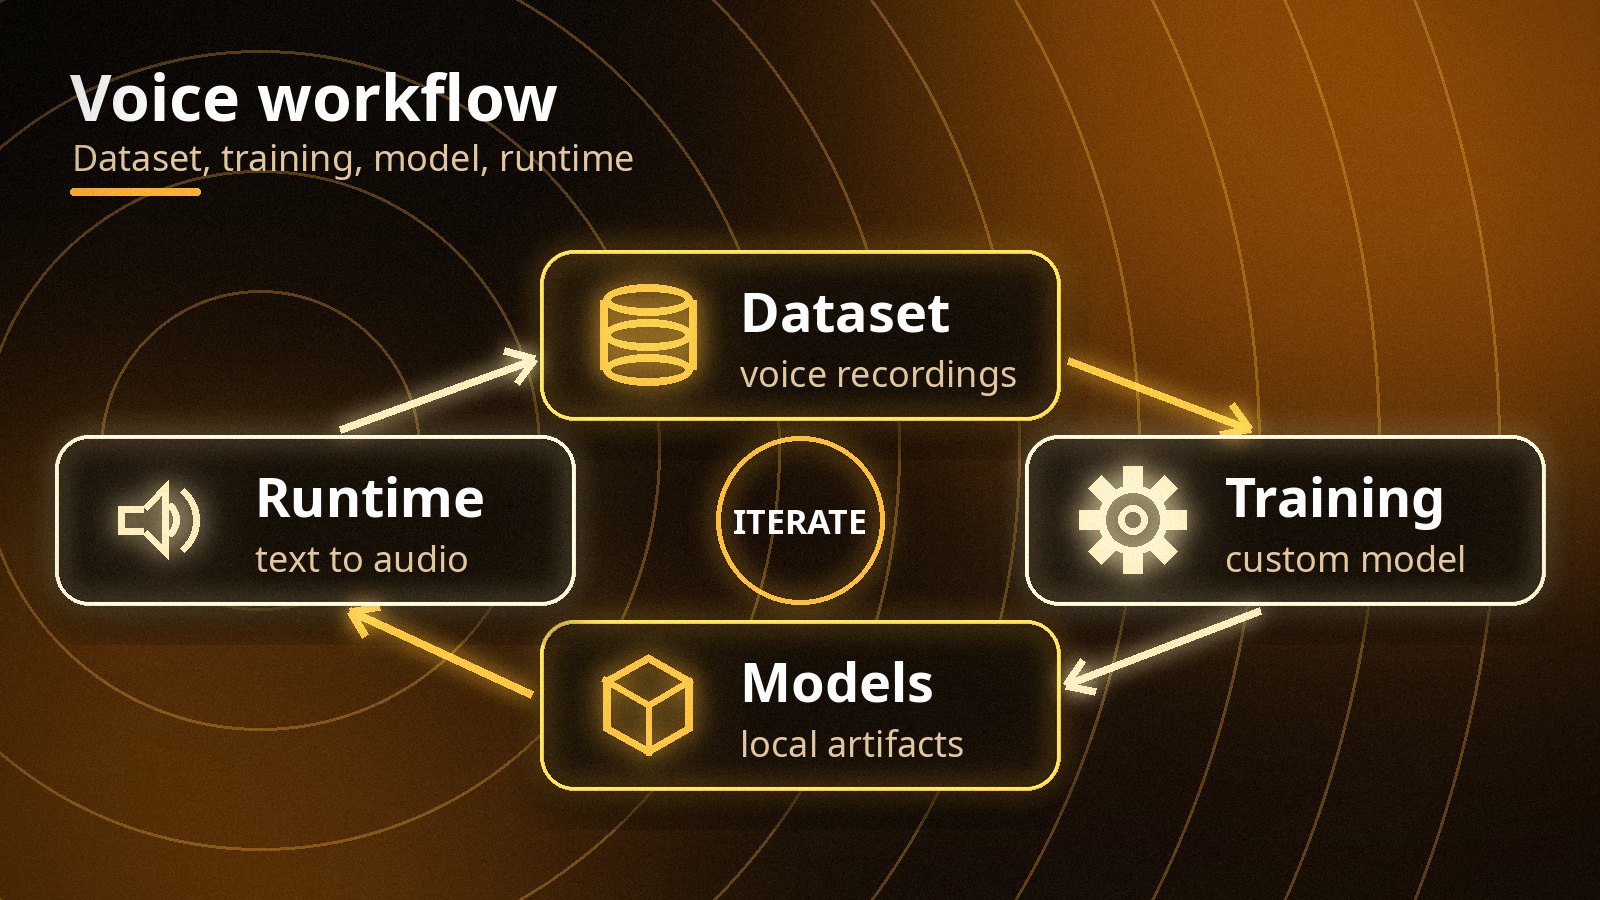
Input text goes to the runtime track, which produces audio with ready models. Separately, a voice dataset goes through the training track and produces a custom model, which the runtime can use. Both tracks share a models folder for local artifacts. The workspace is documentation-first: the READMEs are the planning source while the code is being completed.
Send a direct message about this project and it will be delivered to my email.